- Generating data. First, your data. PMCP accepts data igenerated by the ExPASy PeptideMass program (select "chronological order" retain information about the primary sequence of the protein) in plain text format and copied to a text file. Experimental data may be generated by mass spectrometry, and a list of peaks may be copied to a text file.
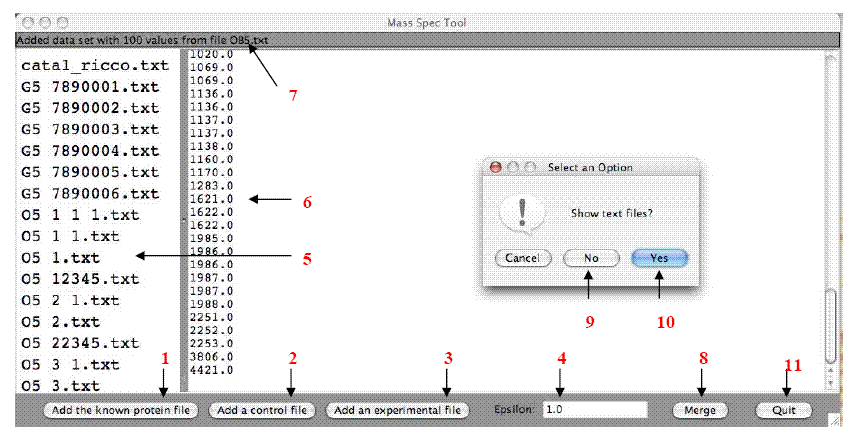
- Data Input into PMCP. (See the figure below)
Files must be saved in text (.txt, not .rtf) format and
inputted in order: Add the known protein first (1), followed by all control
files (2), and finally all experimental files (3). To change the degree to
which peptide masses must match to be counted as identical, enter a number in
the epsilon field (4) -- 1.0 matches peptide masses to the whole number, 0.1 to
the tenths place, etc. As files are added to the program, the file name will
appear in the panel to the left (5), while the text of the file will appear in
the main panel (6). Text at the top of the window monitors the files as they
are added (7). Select "merge" to view the output (8). When prompted for whether
or not you would like to view text files, choose "no" to only view graphs (9)
or "yes" (10) to view all outputs. To quit the entire program, select the
"quit" button at the bottom of the window (11)
- Text Output.
The text outputs are as follows:
- Numerical: All files are sorted by numerical order in adjacent columns in the same window. Matching peptide masses appear on the same line.
- Chronological: The "known" input remains in its original order. For each subsequent file, only those peptide masses that match a peptide mass in the known protein are retained in adjacent columns in the same window. Again, matching peptide masses appear on the same line across columns.
- Non-matching: One window is created for each file containing only the peptides that appeared in the experimental data but not the known protein. The non-matching outputs may be saved as text files and directly read back into the program with another known protein.
- Graphical Output.
The two graphs produced by PMCP illustrate the following:
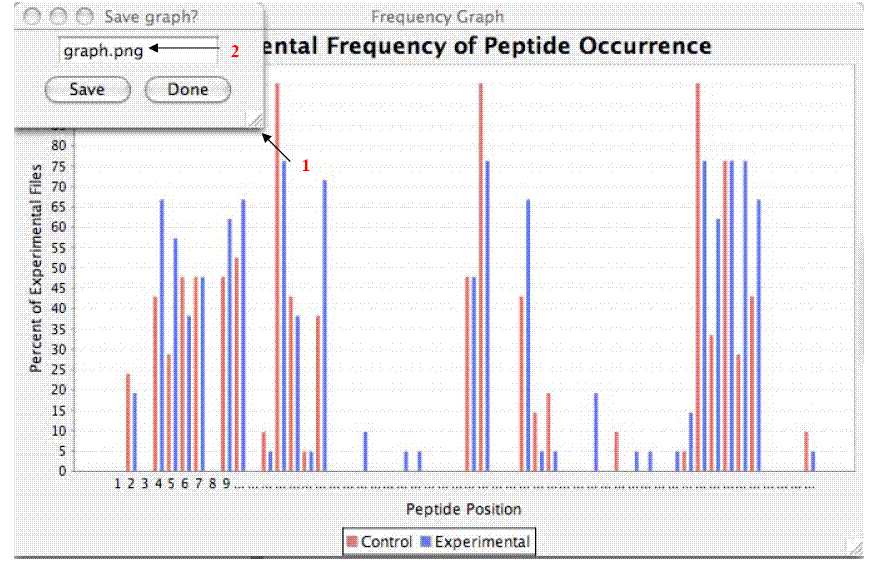
- The percentage of total inputted files that contain each peptide of the known protein, with control and experimental samples appearing side-by-side on the same axes.
- The difference in this percentage between the control and experimental samples for each peptide.
Each of the two graphs (See Figure below) is accompanied by a smaller window (1) that allows it to be saved as a "png" file. To change the file name, change the text in the field in the center of this window (2), making sure to keep the "png" postfix (file type). The default file output location is the directory where the program is saved.